Blog

  • Self hosted mail server – an unexpected solution

    A long time ago, The Daily WTF posted a brillant article called the complicator’s gloves. If you see a spelling mistake in that first sentence, it’s actually an age captcha and you are clearly too young to proceed. Go back to The Daily WTF, spend at least 3 days catching up and then come back to continue reading.

    I think I would have fit right in that team. I would look at that poster and I’d be thinking “gloves are for… losers” as I proceeded to make my home lab even more complicated.

    A couple of years ago I realised that making things complicated comes at a cost. Things break, they take too long to maintain, and they become generally too hard to work with.

    The technical debt became so high that I would have a new cool idea but before I could start, I would remind myself of the two dozen things that I should really do before I put together another half cocked solution.

    Three side projects later and I would be both out of will and energy to do anything else, and the cool idea would go on the ToDo pile, quite often never to be touched again.

    A new approach

    It was time for bold moves. I didn’t need a disk-less docker swarm that PXE-booted on iSCSI from a dedicated ZFS storage server. Neither did I need the ability to PXE-boot repurposed laptops for random experiments.

    Now that ZoL was offering a much more civilised version of ZFS than the mid-0.6 version that I started with, the 16GB of RAM on that file server seemed like a waste for my needs. So I went out and got another 16GB. Anyone remember the good old days you could do that without having to sell a kidney?

    Before I go on and to make sure I don’t sound ungrateful, a big shout out to all the ZoL people who have been saving my… sanity for over a decade now, since those 0.6x days. Snapshots are a godsend in themselves but with the exception of the odd lock-up back in the early days, I never had any issues or suffered any data loss.

    So the plan was to turn that storage server into an all-in-one storage/virtualisation server. That’s where Proxmox comes in. Again. Now at v8, it had also come a long way from the v4 days, when I last run a HA cluster at home.

    With ZFS support out of the box, the decision was relatively easy. Replace the Ubuntu installation with Proxmox, import the old pool, export the old ZVOLs over iSCSI for the swarm, the rest of the shares over NFS and nobody would ever notice we were here.

    To the TrueNAS fans out there who I can hear screaming, yes, one day maybe, when I have a dedicated HBA to pass through and a more uniform disk collection. I wouldn’t mind the convenience of a full blown NAS host.

    In the end there can be only one

    After a short burn-in period, I created a VM with enough resources for all my running containers, fought the bloody raft one last time to get the swarm to accept the new VM as a new master and removed the bare metal hosts from the swarm.

    I don’t remember the specifics but as it had often done in the past, the raft broke. More than once, and I had to roll back to the snapshot and start over.

    Did I promote the new master first or did I demote one of the old ones? I still have the same question I had back then. Is 2 closer to even or 4? Is it just a hit and miss that you get a majority vote and things can actually happen?

    It was finally all done! I now had a lone “legacy” docker swarm master running in a VM on Proxmox. It has been surprisingly stable ever since.

    I suppose if you don’t have too many members pushing, pulling and generally rocking the raft, the raft has no reason to break. It also probably has little reason to break if the members are stable.

    Who’s to say that PXE-booted, single core, Raspberry Pis with iSCSI storage served from a questionable file server were the reason for any instability. We’ll never know… Gloves, remember?

    OK, maybe two, but only briefly

    The next step? While the Jenkins based CI/CD pipeline I had in place did the job, it was a bit too heavy as well as overkill for my little setup.

    With the fear of the raft also fresh in my mind, I had decided that I would replace that last swarm master with a plain old stand-alone docker instance. The existing stacks could then be moved gradually across.

    The mail stack

    You’re still reading and wondering when are we gonna get to the mail server bit? Well, at this stage, the mail server was a stack of Postfix, Dovecot, PostfixAdmin, RoundCube and of course, a MariaDB back end. It lived on the legacy docker server.

    It was put together at the time that a correct SPF record was enough for messages to get through to the big boy mail servers. DMARC and DKIM were being introduced but were not strictly necessary yet.

    Some time later, messages started landing in spam and eventually Yahoo stopped accepting the messages altogether. I didn’t really care. I was hardly ever sending any mails from that server.

    Its main use was system messages for the lab itself and a catch-all mailbox for handing out one-off addresses to questionable registration forms. Sub-addressing (plus-addressing) is the modern way of doing it.

    Now it was its turn to be moved to the new docker server and as usual I looked around to see if anyone more competent has put together a better stack than mine. Plenty of such people out there. There are also plenty of choices too.

    The most popular names seemed to be docker-mailserver, Mailu and Mailcow. All of them are a much more polished variation of what I already had, with Dovecot and Postfix at the core. Nice, familiar, trusted, what’s not to like?

    The new kids on the block

    As I was trying to find out more about each of them, which one would have the smallest footprint and which one would be capable of handling my near-zero load, another name kept popping up.

    Stalwart is a new, all-in-one mail server written in Rust. To paraphrase Sheldon, everything is better in Rust! Better yet, there is also Bulwark, a companion webmail client for Stalwart.

    When I say new, I mean new new, as in v0.16. Many positive reviews out there, with the only red flag being about upgrade trouble. It’s in such an early development stage that the data structures are not guaranteed to remain the same in future versions. In fact the current recommendation is to stick with whatever version you have and avoid upgrades until v1.0 comes out.

    I decided to take the giant leap of faith and potentially risk losing my precious cron and monit notifications. Just kidding. I back those up on a vanilla Dovecot instance using ImapSync. Did you think I’d be that reckless?

    So far they both have been extremely stable and Bulwark is getting very frequent updates. You can tell that they are young projects with the odd basic feature missing here and there but If they continue like this, I’ll be very happy with the choice to switch.

    In terms of features, go read the marketing brochure on one of their sites. For me, the most impressive part was the ease of setup. All web based and all fully integrated. I may regret that web based part when the time comes to migrate, but I guess I’ll burn that bridge when I get to it.

    Set up a domain, give it a token to the DNS server and it goes off and configures everything. It fetches TLS certificates from Let’s Encrypt and it creates all the necessary SPF, DMARC and DKIM records. Even Yahoo was almost happy to accept my emails again. Almost.

    Nearly there

    The final problem with having my mail reliably delivered, was my IP address. My ISP, as any responsible ISP should do, registers residential IP addresses with Spamhaus, and Yahoo was not happy about that.

    I didn’t have too many alternatives. Either fill in the form at Spamhaus and request an exemption for a year or use my ISP’s SMTP relay. I didn’t like the idea of forgetting to renew the exemption and have my mail quietly stop working, so relay it is.

    That’s what I thought, but my ISP had stopped offering the SMTP relay service over a decade ago. What about AWS? Could SES be used with a self-hosted mail server? Well, it does have an SMTP interface so… maybe?

    DNS verification that I own the domain, check! Email verification that am a valid sender, check! Budget check that I can afford 16 cents per 1000 messages, my accountant still has not get back to me on that.

    It was all looking good but did not feel quite right. I was about to look through the SES terms of use when I did a search for SMTP relay services and to my surprise, there are plenty!

    The discovery

    As it turns out, the good vs evil spam battle has given rise to a whole industry of email marketing solutions. From embedded or even stand-alone subscription forms, to mailing list management, to SMTP relaying, these guys offer a full solution.

    Like many other services these days, most of them use a pay as you go model, including a free tier. I thought this is too good to be true. I found a chatbot that turned out to be a human and explained my situation.

    “I’ll be sending a dozen transactional emails a month, on a good month. I’m never really gonna exceed your free tier level. I don’t collect email subscriptions at all but if I did, I’d be using that fancy, double verified, triple confirmed with unsubscribe options and sugar on top, form you talk about.”

    Yes, said Lucas, the human chatbot, just put all that in the “I won’t use your services to spam people, pinky promise” form. So I did… And it was all good… My account got approved and I was finally able to email myself again on my Yahoo account!

    To be fair, Stalwart had done most of the heavy lifting with all the fancy DNS configuration. All I had to do, was add the relay’s domain to my SPF record, and their SMTP server as a relay route.

    Preliminary Conclusions

    This must be the best kept secret out there. A self-hosted mail server is turning into the holly grail of self-hosted because of all the hoops we have to jump through, to have our mail delivered.

    Just like everything else self-hosted however, a thorough evaluation is needed before trusting it with anything important like life and limb, security, privacy, reputational risk, personal and professional, etc etc.

    I can’t ignore the irony that the very services that were created to facilitate the sending of good spam, can be used to solve the problems that bad spam has created for everyone else. I suppose in a way the problem is exactly the same.

    Evaluation

    So why have I gotten this far without naming the chosen service? Because I’m not 100% happy with the one I chose, or should I say, signed up for. It was more of a rush to prove the concept rather than an in-depth analysis that triggered that choice. With the concept proven, now I can start looking closer.

    Their primary focus is marketing emails so the most basic of all email features, delivery failure reports, is not supported. You can check all that online when “evaluating the results of your marketing campaign” but there is no angry sounding email from MAILER-DAEMON, telling you to check your spelling.

    They add a “Sent with xyz.com” footer to the email like they are a giant blooming iPhone. They also add their special magic tracking sauce to see if and when the email is opened and of course all the EU-compliant unsubscribe headers that make Yahoo twitch and ready to pounce.

    There are providers that focus on transactional emails who may be more suited to my needs, and now that the concept has been proven, it should just be a matter of just signing up for the right service.

    What else?

    A final word on SES. I have since found out that it’s a very basic version of all of these services. It does not offer any of the bells and whistles that seem to be ruining my current experience so I will definitely be having a second look.

    Oh, and why do I keep going on about Yahoo? Because it’s my primary email account provider and the strictest of the two that I have an account with. If I can fix deliveries to Yahoo, I’d expect them to work with Gmail as well.
  • Troubleshooting intermittent routing issues

    Quite some time ago, I started noticing random websites failing to load at random times. No real pattern to it. No obvious reason but also no lasting effects. Refresh a few minutes later and everything was back to normal.

    My browser? My network? Their network? All the new fancy cloud related technologies? Asynchronous microservices, serverless functions, NoSQL databases, ephemeral instances and everything else that happens when IT people decide to bring their commitment issues to work…

    There certainly were enough new technologies appearing. Too much scrumminess and agility up in the air. Way too much continuous integration, all the way to the back of the developer’s envelope. Teething trouble I thought…

    Looking at Firefox’s Network Monitor (Ctrl+Shift+E), the main culprits back then were fonts from fonts.googleapis.com and javascripts from one of the gstatic.com domains. Great! The undercover tracking “cookies” were now causing random sites to fail when unavailable. I blamed it on failing CDNs at the time and moved on as the problem gradually went away by itself.

    I may be connecting dots that were never there but some time later, google services would stop responding at times and I assumed the issue was back. Google search, google chat and youtube, all would randomly just stop working.

    The troubleshooting equations started with time and service as parameters. User, device and program were added very soon after. It started with the classic “works for me” responses and escalated to Cluedo style reports. “Google, on the laptop, with Edge is broken again.”

    Down the wrong rabbit hole

    I misinterpreted my trusty Firefox Network Monitor, which showed NS_BINDING_ABORTED errors. Those happen when the user is too impatient and clicks all over the place. Instead I assumed that the NS part meant DNS issues because of course, it’s always DNS.

    Was it Pi-hole? Was the Pi 2B finally dying? Or the 10 year old SD card? Is the latest version finally reaching the hardware limits? Am I even running the latest version?

    So many questions, one simple way to answer them all. Set up an instance in a Proxmox CT, sit back and wait. Did I mention that this process involved A LOT of waiting? The beauty of intermittent problems…

    Well, that didn’t fix it. I very briefly tried running without an ad blocker but that was not an acceptable option, especially not for a long waiting test. I tried AdGuard Home but that didn’t fix it either.

    I tried both Pi-hole and AdGuard with a combination of upstream DNS servers (ISP, google, quad9) as well as a local Unbound instance. Nothing made any difference. combinations returned the same results to the client so I went back to Pi-hole on the Pi 2B.

    At least I ended up with an upgrade to Trixie and valid repositories again. I also kept the Unbound instance, running on the same Pi, because why not add yet another potential point of failure in the chain.

    I was starting to suspect that this time it may actually not be DNS. I don’t know if that has ever happened before but I’m pre-emptively gonna claim first!

    It was around this time that I also started paying attention to the fact that NS_BINDING_ABORTED is not a DNS related issue.

    A more systematic approach

    One of the biggest pains in troubleshooting this, was that by the time I noticed, the time it took me to get annoyed and the time I tried to investigate, I only ever got a few minutes before the problem disappeared.

    I somehow realised that a simple ping was not a representative test to check connectivity to www.google.com. Ping (the program) selects one of the 8 IP addresses at random. So do all other programs, and if they don’t, DNS seems to return the results in random (maybe round-robin?) order.

    Did I mention that www.google.com has 8 A records? So does www.youtube.com. Some sort of redundancy I guess and a natural, external load balancer…

    dig www.google.com
    ...
    ;; ANSWER SECTION:
    www.google.com. 706 IN A 142.251.150.119
    www.google.com. 706 IN A 142.251.155.119
    www.google.com. 706 IN A 142.251.156.119
    www.google.com. 706 IN A 142.251.157.119
    www.google.com. 706 IN A 142.251.153.119
    www.google.com. 706 IN A 142.251.154.119
    www.google.com. 706 IN A 142.251.151.119
    www.google.com. 706 IN A 142.251.152.119

    I soon was able to confirm that whenever I was having trouble with a service, at least one of the IP addresses was not reachable. No ICMP responses, no traceroute, no response to an http request nothing.

    I needed a way to check this without having to very quickly type ping commands and it would certainly help to keep track of when it happens, how often and how long it lasts.

    Gatus

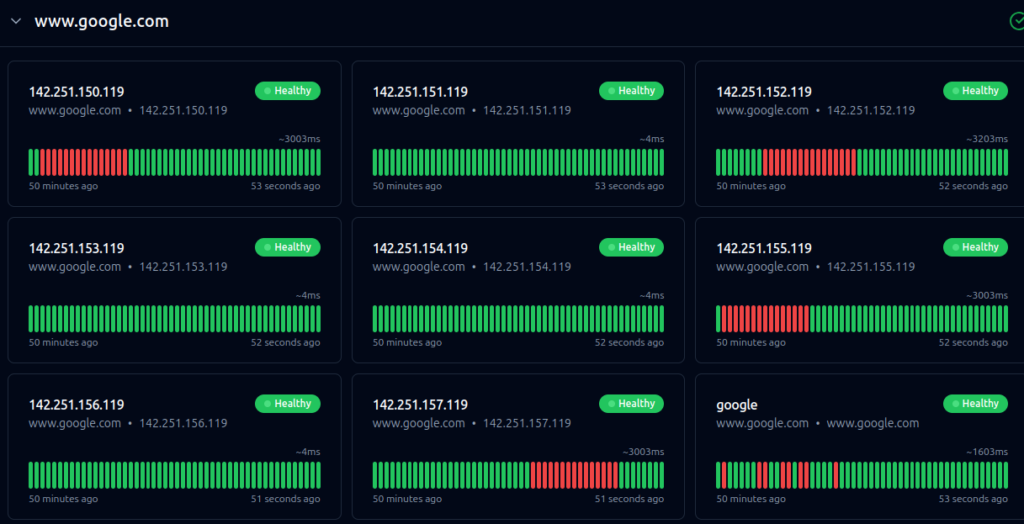
    Gatus to the rescue! I don’t know much about their hosted service. I needed to monitor google from my location so I went with a local docker instance and boy, has it delivered! Here is a gist of the config I used to simply ping the 8 IP addresses every minute.

    Is it still a plug if I praise someone else’s service? Who cares. I’m happy with the few features that I have used so far and I will most certainly be looking at it further. That feature list looks impressive!

    Any conclusions?

    What have I found out so far? Well, I’m not going (completely) mad. The red bars do exist but that’s as far as the insight goes for now.

    • They last a VERY consistent 15 minutes
    • They don’t seem to be random. Sometimes it’s all fine for a couple of days, sometimes they happen multiple times a day.
    • The outages by IP, seem to be (loosely) connected. Quiet days are quiet across the board. On busy days the outages seem to happen in sequence.
    Gatus dashboard from 22 September 2026
    Gatus dashboard from 22 September 2026

    If it was any other website or service, I would argue that their service rollout process is to blame, or their network update process, or their failover process or something along these lines.

    We are talking about google services however. That’s the part that does not compute. It’s not that they don’t have youngsters that very enthusiastically push the wrong button. It’s that if a technician has beans in the evening, the news reports “excessive methane levels in the data centre” the next day. It could be my ISP but then it would be the national news instead…

    That leaves 2 options. Either the issue is indeed on the side of my ISP but only affects a small subset of users, my network “neighbours” so to speak, or the issue is in my own network.

    More data is required and more may soon be coming. I’ve asked the question on my ISP’s community forum and people have already offered to monitor from their own connections. There will probably be a 2nd part to this with further findings.

    Alternate theory

    There is of course a slight chance that they intentionally bury all the google outage reports from the search results. That means that yet another one of my conspiracy theories has been confirmed and this blog will never be popular now.

    Anyone getting to find and read this entry constitutes and actual paradox and I need to stop writing and go find my tinfoil hat at once. So long and thanks for all the fish!

  • BI on a shoestring – an ode to materialised views

    Some background info

    As I may or may not explain on some other post, some other day, I run my home lab on hardware that’s well past the “obsolete” stage and marching full speed towards becoming “vintage”.

    Said lab, hosts all sorts of little services, private and public, including this here, marvellous website as well as a docker instance of BrickSync, a great little piece of software that keeps our BrickOwl and BrickLink stores in sync.

    On a routine search for my lost disk space, I (re)discovered that BrickSync spits out a snapshot of the store inventory in XML format every time an update was triggered. Either by an order or by me. It also saves a copy of every order in XML format.

    All in all, I discovered over 20 GB worth of XML files that contain a nearly full history of my store. A short python time later and I had a POC that could walk through all the files and dump all the data. Now what?

    The failed attempt

    A little voice in the back of my head had been shouting Elastic, which I hadn’t used before. A chat with a friend confirmed the idea. A ton of little files, ingested and turned into useful, searchable information. Exactly the task Elastic was made for.

    So, off I went to set up a stack on my poor little home lab. That’s when I was reminded that Elastic is meant to run on proper server hardware. I kept adding memory, trying to get it to do something useful, and I eventually got to that point with 4 GB of ram.

    Yes, it run and yes, it looked like it was doing something but not much and not fast. Compared to everything else on that server, its footprint looked like Bigfoot was stepped on by a dinosaur, and the spatter was causing OOM kills among the rest of the services.

    Back to the drawing board

    Then I thought my data is already very structured. Do I really get much benefit from using Elastic? How about pushing the data in some database, MariaDB being the prime candidate, and then treating it like the time series it is, maybe using Prometheus and Grafana.

    While researching the subject, the Postgres name kept popping up and I decided to give it a shot. I have a couple of instances running but never developed for it. A quick setup and a quick update to the python scripts and data was loading in the background while I continued researching the Prometheus – Grafana setup.

    As it turns out, Prometheus is itself a database. A Time Series Database to be precise and as it turns out, Postgres also has a time series extension, TimescaleDB. The things you find out if you RTFM first…

    By this point, I already had nearly 50 million records imported and I had already discovered that Grafana can actually pick up data directly from Postgres. I decided to skip the completely unfamiliar to me, Prometheus step, and leave that lesson for another day.

    My thought process in roughly this order:

    • This is SQL. I know this!
    • The Grafana query builder is a bit of a pain. I’ll create views in Postgres.
    • These views are kinda slow. Since I don’t have real time data to worry about, I could cache the view results into a table…
    • Hey look! Materialised views!

    Where were those when I was young? That’s similar to the SQL Server Indexed Views, right? Is that where the idea of cached views came from? This brain could do with some defragmenting and re-indexing…

    What did we achieve?

    What a fantastic thing those materialised views! Aggregate 50 million rows in 2, 3, 4 different ways, base your queries on those and get sub-second responses!

    Refreshing these views takes a few minutes on this beast of a system, but new data is only available a few times a day so daily updates are more than enough. Those will probably be scheduled to run during the night.

    The current setup consists for one Postgres and one Grafana instance, each allowed 512MB of ram. I can get the Grafana container killed if I open a bunch of pages back to back but I have not yet seen the Postgres container die.

    What’s next?

    The TimescaleDB extension might still come in handy. Incremental updates to the materialised views, time buckets and alleged space savings with columnar storage compression are definitely worth checking out.

    For the front end, something lighter than Grafana might be worth exploring. At the moment it feels like I’m using a sledge hammer to present data straight out of views. Maybe something based on Apache ECharts would be enough. A project for when we need to recover server resources.

    Why?

    So what does it do? Well it does exactly what it was meant to do. It provides very clear and valuable insights into the inner workings of an AFOL’s mind. It also highlights other mysteries of the lego world.

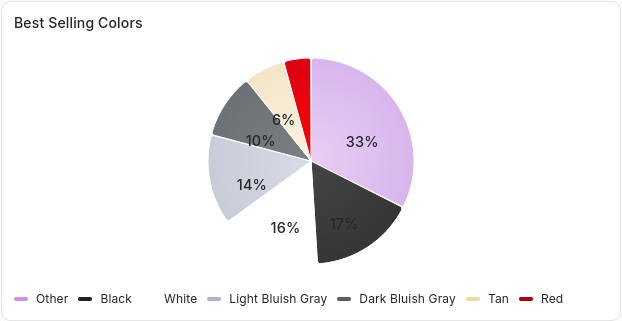
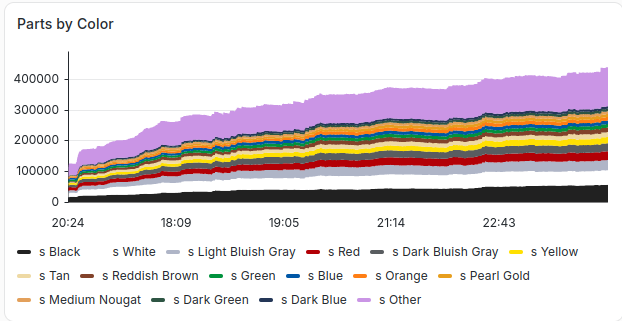
    How, for example, when black, white and grey parts only make up a quarter of the store stock, they account for over half of the sales. Or how when over half of the sales are of black, white and grey parts, all the things that people build and share are so colourful…

    Part Count by Color
    Part Count by Color over the last 5 years. X-axis could do with some more formatting
    Parts sales by color

    It does more and it can do even more. My next challenge is to determine what other data can be extracted and visualised, and more importantly, find out in what way is it of any value.

    In any case, finally getting to play with Postgres in a non-superficial way is a win in itself. It seems to have a very slightly larger idle footprint than MariaDB and it has been a very well behaved tenant on this limited server so far.

    Materialised views were a very nice, unexpected little surprise. Apparently Postgres has a full meme worth of such features waiting to be explored. Can’t wait!

  • Raspberry Pi as HDMI-CEC to IR Bridge

    Note: This article was first published in June 2016, in a previous incarnation of this blog and has been rescued using the Way Back Machine.

    The Problem:

    I recently got an IP-TV subscription and the set-top box delivered by my provider does not support HDMI-CEC. The remote control included in the package has limited “smart” functionality – as in, it can be configured to somewhat control your TV – but that’s far from ideal, or functional if your set-up consists of anything more than a TV. In my case the set-up is not that much more complex. It consists of a TV, an AVR receiver and an OpenELEC media player. With the help of a Pulse Eight USB – CEC Adapter, I’ve been able to happily control them all from my TV remote over HDMI-CEC.

    The new addition to the group was causing me a bunch of headaches. Not only did I need the set-top box remote to change channels, but I also needed the AVR remote to select the correct input. Using a second HDMI input on the TV could solve that problem but the ARC channel from the TV to the receiver is not pass-through. My Samsung TV seems to pre-process audio to either PCM or DTS NEO 2:5.

    The Solution:

    Well, the most obvious one would be a Logitech Harmony but where would the fun be in that? Nothing to break open, nothing to tinker with and I would have to keep the set-top box in a visible place to maintain line of sight. An Arduino came to mind (and I may still get back to this idea – more on that further down), but at the time is sounded like a lot of work.

    Then I remembered that the Raspberry Pi HDMI port supports CEC and that while I was setting up the OpenELEC player, I had to set the correct address for the AVR to switch to the right input. That’s when the idea started becoming simple. Connect the Pi to a free HDMI port and make it pretend to be the set-top box. Listen to the CEC commands coming from the TV and translate them to IR commands using LIRC.

    All ingredients were available. The good people of Pulse Eight have made libCEC available, including sample clients and there are a ton of tutorials out there on how to use LIRC to make an IR Remote out of a Raspberry Pi so I got to work.

    The Hardware:

    The transmitter circuit is straight forward. A couple of IR LEDs, a current limiting resistor and an NPN transistor that can be switched at 3.3V. The 2N2222 seems to be the transistor of choice in most circuits I came across but the BC338 that was in my box of loose components works nicely too. Any resistor below 500 Ohms, should be fine. It could even be skipped if the power supply is strong enough to prevent a voltage drop on the 5V line. Of course the range of the transmitter and the lifetime of the LEDs depend on that resistor so pick one that suits your needs. The capacitor is added as extra protection against that voltage drop and again, it can be omitted.

    A piece of scrap strip-board and a quick soldering job and I had a prototype. I didn’t have any IR LEDs around but luckily enough my TV came with an “IR Extender” module which seems to contain two IR LEDs in a nicely polished package with a long wire and a 3.5mm jack.

    If it’s not obvious from the picture, the resistor and capacitor were added after the initial “board design”. On the bench, the circuit worked without them but when I tried powering the Raspberry Pi from the USB port of the set-top box, the current wasn’t enough and the Pi kept rebooting every time I pressed a key on the remote.

    The Software:

    LIRC:

    I started with a standard Raspbian Jessie installation, at least for the purposes of this story. I actually net-boot Raspbian from NFS using u-boot but the result is the same and that’s perhaps a story for another entry. The LIRC installation and configuration is extensively covered online so I will just highlight the key steps. Using a DIY transmitter means that the lirc-rpi driver was needed. This driver creates a virtual device using two of the GPIO pins on the Raspberry Pi. To enable that, I needed to load the lirc-rpi overlay at boot time by adding the following line in config.txt.

    dtoverlay=lirc-rpi

    This defines the hardware for the kernel and allows the lirc-rpi driver to be loaded and the /dev/lirc0 device to be created. The LIRC installation is standard and there are plenty of places where “remote” definitions can be found for the lirc.conf file. I found one for my set-top box on a Gist from proycon. With the original remote and an IR receiver, such a configuration file can also be created with the irrecord utility which is part of the lirc package.

    CEC Client:

    At this point I had working hardware and LIRC configured. I was able to issue commands to the set-top box from the command line using the irsend utility and all I needed was to tap into the incoming HDMI-CEC messages and handle those. libCEC and the utilities that come with it are great. The cec-client made it simple to manually play around with CEC messages until things started making sense. With the help of cec-o-matic, I was then able to create a list of commands that I needed to send and consume in order to bring the TV, AVR and set-top box in sync.

    Sample clients are also provided in different languages. Since I would be coding on the Raspberry Pi over SSH sessions, I opted for python. Now, python is by far not my strongest skill and I kind of got lost trying to get the python libraries working by using the libCEC packages. Something about Swig is mentioned but I didn’t know how exactly to get an API definition using that. I took the next easiest route, I cloned the libCEC repository, followed the instructions and built the library from source. The python client worked straight away.

    There are a couple of things that needed doing to the client to get the functionality I wanted out of it. First of all, I wanted it to handle key pressed events so I went ahead and mapped the key pressed events in KeyPressCallback to irsend commands using a whole list of these:

    if key == 0:
    os.system("irsend SEND_ONCE VIP1853 OK")
    elif key == 1:
    os.system("irsend SEND_ONCE VIP1853 UP")

    For some reason that I didn’t really look into, that callback function handles both key-pressed and key-released events with only the duration to distinguish between them. On top of that, some keys only raise a single event that doesn’t start at duration 0. This may be something done by my TV, libCEC or the protocol itself. In any case, with these conditions at the top of the callback, I was able to filter the events I wanted to handle:

    if duration == 0 or ((key == 150 or key == 145) and duration == 500) or (key == 69 and duration >= 1000):

    The next thing to do was to make the Raspberry Pi announce that it’s connected to the HDMI port that is used by the set-top box. This tricks the TV and the AVR to switch to the “correct” input when I select the Raspberry Pi from the TV’s CEC menu. For that, I needed to override the auto-detected physical address of the client at start-up in the SetConfiguration function:

    self.cecconfig.iPhysicalAddress = 0x2200

    0x2200 corresponds to the DVD input of my AVR (2.2.0.0), where the set-top box is connected and that was it! The client did 99% of what I wanted so I went ahead and created a daemon start-up script for it so that it starts and runs in the background at boot time. The start-up script needs to be copied to /etc/init.d/ and scheduled by running:

    sudo update-rc.d cecClient.sh defaults

    The Result:

    The remaining 1% consisted of three problems. First, the python client wouldn’t stay running because the main loop was expecting input from the console for its standard functionality. Since I’m running the client as a service, that wasn’t needed any more and commenting out that raw_input line solved the issue.

    METADATA-START

    The second was that by default, libCEC tries to power up my AVR when I switch to the Raspberry Pi. For some reason, it’s unable to get the correct power status from the AVR and issues a POWER ON command which more often than not actually puts my AVR on stand-by. My TV also seems to have trouble handling the power status of the AVR correctly so I’m suspecting Pioneer’s CEC implementation may be the issue. I was able to clear the automatically-filled device list of wakeDevices but I guess I’m doing it at the wrong place because it still happens once after the client starts. Since I’m not rebooting the Pi, this is good enough for me.

    The last problem was power control of the set-top box. Since communication is only possible in one direction, I can’t check if the set-top box is powered on or gone to stand-by mode. I can’t even check the status of the HDMI port for that because when on stand-by, the set-top box goes into screensaver mode and the HDMI port remains active. To work around this, I mapped the IR POWER button to the unused CEC Tools menu option and now power can be controlled by a couple of button presses.

    With all that in place, I’m now again able to hide away all other remote controls and control everything from a single one. Without line-of-sight needed, the set-top box could also join the rest of the cable mess in the drawer under the TV and stay out of sight.

    I have uploaded the LIRC configuration files as well as the modified python client and daemon script on Github for anyone interested in trying this out.

    A warning for the adventurous: the GPIO port on the Raspberry Pi is as sensitive to over-voltage as everyone claims. Even a charged capacitor is enough to damage the BCM2708 SOC. I found out the hard way by plugging in the board on the Pi the wrong way around.

    Further Ideas:

    Inspired by the Pulse Eight USB – CEC Adapter, I am considering an Adruino based version of this, using the same pass-through trick so that an extra HDMI port isn’t occupied. With a custom Arduino implementation, such a device could be used to emulate and control multiple non-CEC capable devices, be instantly on and consume around 50mA instead of the Pi’s 500(ish). Libraries are already available for both CEC and IR, there are examples of the circuit needed to interface with CEC and a prototype interface can be done using half of a standard HDMI cable. The discouraging part is having to do programming and debugging in front of the TV. It may be an idea for a Kickstarter project or for Pulse Eight to introduce as a new product.